The model returns probabilities, not a review comment. A rule like weakens_tests >= 0.6 → block is one line of YAML.
01 · Context
A study on top of Anthropic's source-control redesign.
Anthropic described rebuilding source control around agents: a system called Scion built for roughly thirty thousand merges a day, where most commits are written by models and humans no longer sit in the loop of every merge. — Redesigning source control at Anthropic, Anthropic Engineering, 13 Oct 2026. Paraphrased; read the original.
That post is about storage and history. It leaves one question open, and it is the one mergeone exists to test: at thirty thousand merges a day, who decides what merges? A human cannot read them. A frontier model is too slow and too expensive to ask about every PR, and it answers in prose that cannot be put behind a rule. This site is the write-up of an experiment on the alternative: a small, fast, typed decision layer — a System One model that answers fixed questions with calibrated probabilities — placed in front of trunk as a gate. mergeone is the open-source gateway that came out of it. Everything below is reported the way it came out, including the three runs that failed.
Two days later the Claude Code team described how code is reviewed at that volume: daily landed changes went from about 2,500 in May to over 30,000 in September, most PRs merge with at most one human in the loop, and a classifier — not the author — sets each change's risk tier. — How the Claude Code team does code review, claude.dev, 15 Oct 2026. Paraphrased; read the original.
That is the layer mergeone measures, and the number this site calls ×1 is their September. The post stacks seven layers in front of trunk; the fifth is a classifier deciding how many humans a change needs, and mergeone is that decision as a typed, calibrated, logged call with a policy on top. What the post leaves open is the case run 3 found most often: two agents landing the same change twice. Run 6B is the measurement of that gap; notes.

Our reading of a public post, not an affiliation. The seven layers are theirs; the highlight is where this benchmark's question sits.
02 · Design
Many agents, many PRs, one gate.
Fig 2 is the system under test. Agents open PRs; each PR is rendered once and sent to a decision model that answers five typed questions in a single call; calibration turns answers into probabilities; a policy file turns probabilities into a verdict; a planner groups open PRs into waves that can land together. Every box is a file in the repository; every number is measured. The feedback loop at the bottom is the part that makes it a study rather than a product: a pre-registered benchmark decides whether any of this is allowed to claim anything.
Agents open PRs through GitHub or ask the gate directly over MCP. Each PR is rendered once and sent to a System One model that answers five typed questions in a single call; isotonic maps turn the answers into calibrated probabilities; your .mergeone.yaml turns probabilities into a verdict. Open PRs are grouped into non-conflicting waves so hundreds can land in parallel. Every verdict and its exact input land in the gatelog. Human outcomes and the pre-registered benchmark feed back into calibration and thresholds — which is why the policy file is the only thing you ever edit.
03 · The gate
Not a queue. A gate.
PR state ──▶ decision model ──▶ calibrated probabilities ──▶ policy rules ──▶ verdict + route
             (Jev / Haiku)        is_logic_change      0.91     .mergeone.yaml     pass · hold · block
                                  weakens_tests        0.07                        auto-merge · human · domain-review
                                  message_matches_diff 0.88
                                  touches_concurrency  0.63
                                  needs_human_review   0.41
                                             └── every decision + its input → gatelog
Typed, not prose
Calibrated before rules run
0.6 means sixty percent. Isotonic maps fitted on labelled history ship with the binary; raw ECE 0.17 becomes 0.03.
Fail closed, log everything
Model down? The PR holds for a human. Every verdict is stored with its exact input, because a System One model gives no rationale.
Landing plans, not serialisation
Hundreds of open agent PRs become waves of non-conflicting changes that land in parallel; one typed question catches semantic conflicts files cannot.
04 · Evidence
Six runs, seven results, pre-registered. Three failed, two half-failed, two passed.
gatebench is the protocol: every run's hypotheses, thresholds and data rules are committed before any model is called, and every deviation is dated in a changelog. Results are published whichever way they fall. Candidates are System One models (Jev; from run 4, Perplexity's open-weight deciders), a small LLM (Claude Haiku 5.5) and a rules floor; frontier models are never candidates.
Run 1 · negative
Can a diff predict a 30-day revert?0.010PR-AUC · base 0.0075
40,000 Kubernetes merges. Rules, gradient boosting, Haiku and Jev are indistinguishable from chance. The signal is not in the pre-merge state.
results/run1Run 2 · positive
Can it answer typed triage questions?0.87–0.96ROC-AUC vs judge
Five questions in one call. Jev meets the bar on 5/5 at 347 ms and $0.074 per thousand; Haiku 4/5 at 1,067 ms. Calibrated ECE under 0.05.
results/run2Run 3 · negative
Does it predict rejection of real agent PRs?0.55ROC-AUC · bar 0.70
2,196 agent PRs across 26 public repos. Of 200 closures classified, 67% were superseded, duplicate or direction; 19% quality. A diff cannot see that someone else landed it. Jev did pass 100× load: p99 417 ms, zero errors.
results/run3Run 4 · mixed
Can a PR memory catch the duplicates?0.83–0.87pair ROC-AUC · bar 0.80
Three System One models tell two PRs are the same change on held-out repos; the LLM judge (0.76) does not. The retrieval that proposes the pairs finds only 55% of confirmed duplicates (bar 60%), so memory ships opt-in.
results/run4Run 5 · mixed
Does a flag mean more review?0.76flag ⇒ more review, AUC · bar 0.70
Pre-registered this time: calibrated needs_human_review predicts ≥ 2 force-push rounds for Jev and the 4B open-weight pplx-flash. Retrieval v2 reaches recall@5 0.66 (bar 0.70) in 3.3 ms p99. Hosted Perplexity loses 71% of calls at 100× to a per-org rate limit.
Run 6A · negative
Does self-hosting the open weights clear the scale bar?160 msp99 at 30× on one H100 · 100× ✕
Same 4B model, our GPU, vendor code. It answers like the hosted endpoint on 95% of argmaxes but not within the Δp bar; one L4 breaks at 10×, one H100 carries 30× at 160 ms and times out 30% at 100×. Batching did nothing — the limit is compute per request.
results/run6Run 6B · positive
When it holds a PR as a duplicate, is it right?98 / 100holds that were right · bar 0.60
100 blind-labelled holds: 44 are the same change (bar 0.30), 54 are pointers the author should have seen first — backports, promotes, competing fixes, follow-ups — and 2 are false alarms. A second labeller agrees at κ 0.77. The pool size is not the lever; $0.0004 per PR. A hold never closes a PR: half the time the right move is a link.
results/run6 · part B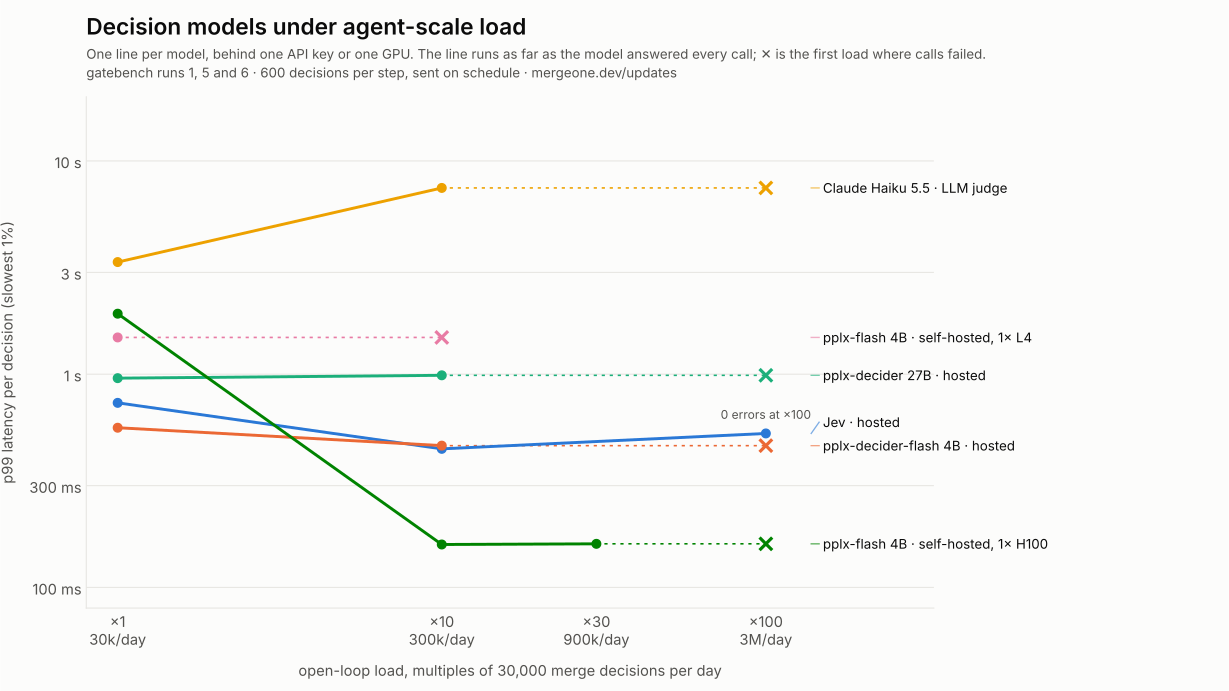
Run 3's labels are worth a second look: when agent PRs are closed, it is mostly not because the code is wrong. That finding did more to shape the product than run 2's good numbers — it is why run 4 exists. Run 4 then split cleanly: the uncertain part (can a cheap model tell two PRs are the same change?) is a yes from three vendors; the part built in an afternoon with fixed weights (which PR to compare against) is the bottleneck, and it caps everything downstream. Run 5 replaced the retrieval and found the next wall: the answer is usually in the top 20, one cut-off too deep. Run 6 rented the GPUs and found that open weights move the ceiling from the vendor's rate limit to your card count; its second half widens the pool and asks two blind labellers whether the holds are right.
05 · What survives
Claims this page is allowed to make.
✓
Typed triage works at System One speed and cost.
Five calibrated questions per PR, ~350 ms, $0.07–0.09 per thousand, 0.87–0.96 AUC against a strong judge (run 2); 100× agent-scale load with zero errors (runs 1–3).
✓
One 2-vCPU box handles 30 million decisions a day.
Open-loop replay at 350/s, p99 441 ms, re-proved by CI on every push. The Anthropic figure is 30 thousand.
✕
The gate does not predict reverts.
Run 1. Nothing in the diff does; we stopped trying.
✕
The gate does not predict whether a project will take an agent's PR.
Run 3. Most rejections are coordination — superseded, duplicate, direction — which one diff cannot show.
✓
A cheap model can tell two PRs are the same change.
Run 4: same_change(A,B) at 0.83–0.87 AUC for three System One models, including an open-weight one, on maintainer-confirmed supersedes. The LLM judge fails the bar.
✕
The memory does not yet find the right PR to compare.
Run 4: retrieval recall@5 0.55 against 0.60, p99 198 ms against 20. Verdict-level gains land at a third of the bar. Shipped behind memory.enabled, opt-in until a retrieval passes.
✓
Flagged PRs go through more review rounds.
Run 5, pre-registered: AUC 0.76 for two System One models; the free rules floor is 0.73, so the model's value is the typed reason, not the score.
✕
No single box clears 100× — hosted or self-hosted.
Run 5: hosted Perplexity refuses 71% of calls above 10 rps/org. Run 6A: the same weights on one L4 break at 10×, on one H100 at 100× (30% timeouts). Batching does not help; compute per request does. Only the hosted System One model passes 100× on one key.
✓
Self-hosted open weights are the fastest row that exists.
Run 6A: one H100 answers at 160 ms p99 through 30× with zero errors — under the hosted endpoint at every load it survives — for $0.11 per 1k PRs, 4.6× hosted list price. What you buy is the absence of a per-org ceiling, not a discount.
06 · Use it, or check it
The agent asks before it merges.
mergeone is an MCP server. Register it once, add one line to your agent's instructions, and every merge goes through the gate instead of around it. The same calls exist over HTTP for everything else.
# register
claude mcp add mergeone -- mergeone mcp --policy .mergeone.yaml

# CLAUDE.md
Before merging, call gate_decide. Merge only on "pass".

# response
{ "verdict": "hold", "route": "human",
  "rule": "message-mismatch",
  "probs": { "message_matches_diff": 0.31, … } }

# replicate the benchmark (every table, one command each)
git clone https://github.com/haalp/mergeone && cd mergeone
python -m mergeone.cli report results/run2 --v2
python -m mergeone.cli report results/run3 --run3